CTO & Co-founder of Visivo
DuckDB Dashboard Visualization for Lightning-Fast Analytics
How to run DuckDB's in-process analytics engine behind a Visivo dashboard: fast queries on one machine, without a warehouse or a cluster.
You do not need a cloud warehouse or a distributed query engine to get fast dashboards. DuckDB runs inside one process on one machine, and Visivo renders dashboards straight from it. Forrester research found that between 60% and 73% of enterprise data goes unused for analytics, often because the infrastructure around it makes exploration hard.
The pair gives you sub-second query performance on billions of rows, all on a single machine, including your laptop. This post walks through DuckDB as the analytical engine and Visivo as the visualization layer: setup, models, the dashboard, tuning, deployment and tests.
What DuckDB does well
DuckDB is an in-process SQL OLAP database: SQLite for analytics. There is no server process. It runs inside your application, so there is no network hop and nothing to operate. Its columnar, vectorized execution engine is built for the scans and aggregations a dashboard runs.
We have made the same argument in lightning-fast embedded dashboards and modern data stack alignment.
What makes it a good fit for dashboards:
- Columnar storage built for aggregations
- Vectorized execution that processes data in chunks with SIMD instructions
- Zero-copy data sharing with Python, R, and other languages
- Direct querying of Parquet, CSV, and JSON files with no load step
- Memory-efficient processing of datasets larger than RAM
The result is query performance that often beats distributed systems costing thousands per month, on your local machine. A simpler system is also easier to keep correct. Gartner notes that "Data quality issues cost organizations an average of $12.9 million annually," and overly complex systems that are hard to maintain are a common cause.
Setting up DuckDB with Visivo
Add DuckDB as a source in your Visivo project:
# project.visivo.yml
name: DuckDB Analytics Dashboard
cli_version: "2.3.0"

sources:
  - name: analytics_db
    type: duckdb
    database: ./data/analytics.duckdb
    connection_pool_size: 2 # Adjust based on workload

defaults:
  source_name: analytics_db
Creating the DuckDB database
Create the database file and load it from CSV and Parquet:
import duckdb

# Create or connect to DuckDB database
conn = duckdb.connect('./data/analytics.duckdb')

# Create tables from CSV files
conn.execute("""
    CREATE TABLE IF NOT EXISTS sales AS
    SELECT * FROM read_csv_auto('data/sales_*.csv', header=true);

    CREATE TABLE IF NOT EXISTS products AS
    SELECT * FROM read_csv_auto('data/products.csv', header=true);

    CREATE TABLE IF NOT EXISTS customers AS
    SELECT * FROM read_parquet('data/customers/*.parquet');
""")

# Create indexes for better performance
conn.execute("""
    CREATE INDEX idx_sales_date ON sales(order_date);
    CREATE INDEX idx_sales_product ON sales(product_id);
    CREATE INDEX idx_customers_region ON customers(region);
""")

conn.close()
Loading data from multiple sources
DuckDB reads local tables, Parquet on S3 and a remote CSV in one query, which keeps Python data pipelines short:
name: model_example

sources:
  - name: local-duckdb
    type: duckdb
    database: local.duckdb

models:
  - name: unified_sales_data
    source: ${ref(local-duckdb)}
    sql: |
      WITH local_sales AS (
        SELECT * FROM sales
        WHERE order_date >= '2024-01-01'
      ),
      s3_historical AS (
        SELECT * FROM read_parquet('s3://bucket/historical/sales_*.parquet')
        WHERE order_date < '2024-01-01'
      ),
      reference_data AS (
        SELECT * FROM read_csv_auto('https://api.example.com/reference.csv')
      )
      SELECT
        ls.*,
        rd.category_name,
        rd.category_group
      FROM (
        SELECT * FROM local_sales
        UNION ALL
        SELECT * FROM s3_historical
      ) ls
      LEFT JOIN reference_data rd
        ON ls.category_id = rd.category_id
Building the dashboard
Data models
Put the aggregation in the model, where DuckDB does it fastest:
name: model_example

sources:
  - name: local-duckdb
    type: duckdb
    database: local.duckdb

models:
  - name: sales_summary
    source: ${ref(local-duckdb)}
    sql: |
      SELECT
        DATE_TRUNC('day', order_date) as date,
        product_category,
        sales_region,
        COUNT(*) as order_count,
        COUNT(DISTINCT customer_id) as unique_customers,
        SUM(order_value) as total_revenue,
        AVG(order_value) as avg_order_value,
        PERCENTILE_CONT(0.5) WITHIN GROUP (ORDER BY order_value) as median_order_value,
        PERCENTILE_CONT(0.95) WITHIN GROUP (ORDER BY order_value) as p95_order_value
      FROM sales s
      JOIN products p ON s.product_id = p.product_id
      JOIN customers c ON s.customer_id = c.customer_id
      WHERE order_date >= CURRENT_DATE - INTERVAL '90 days'
      GROUP BY 1, 2, 3

  - name: real_time_metrics
    source: ${ref(local-duckdb)}
    sql: |
      WITH latest_hour AS (
        SELECT
          DATE_TRUNC('minute', created_at) as minute,
          COUNT(*) as transactions,
          SUM(amount) as volume
        FROM transactions
        WHERE created_at >= CURRENT_TIMESTAMP - INTERVAL '1 hour'
        GROUP BY 1
      )
      SELECT
        minute,
        transactions,
        volume,
        SUM(transactions) OVER (
          ORDER BY minute
          ROWS BETWEEN 4 PRECEDING AND CURRENT ROW
        ) as rolling_5min_transactions
      FROM latest_hour
      ORDER BY minute DESC
Insights
Define Insights on top of sales_summary:
insights:
  - name: revenue-trend
    props:
      type: scatter
      mode: lines+markers
      x: ?{ ${ref(sales_summary).date} }
      y: ?{ ${ref(sales_summary).total_revenue} }
      name: ?{ ${ref(sales_summary).product_category} }
      line:
        shape: spline
        width: 2
      marker:
        size: 6
      hovertemplate: |
        <b>%{fullData.name}</b><br>
        Date: %{x|%B %d, %Y}<br>
        Revenue: $%{y:,.0f}<br>
        <extra></extra>
    interactions:
      - split: ?{ ${ref(sales_summary).product_category} }

  - name: customer-distribution
    props:
      type: pie
      labels: ?{ ${ref(sales_summary).sales_region} }
      values: ?{ ${ref(sales_summary).unique_customers} }
      hole: 0.4
      textposition: outside
      textinfo: label+percent

  - name: order-value-median
    props:
      type: bar
      name: Median
      x: ?{ ${ref(sales_summary).product_category} }
      y: ?{ ${ref(sales_summary).median_order_value} }
      marker:
        color: "#3498db"

  - name: order-value-p95
    props:
      type: bar
      name: 95th Percentile
      x: ?{ ${ref(sales_summary).product_category} }
      y: ?{ ${ref(sales_summary).p95_order_value} }
      marker:
        color: "#e74c3c"
Assembling the dashboard
Group the Insights into charts and lay them out:
name: dashboard_example

charts:
  - name: main_revenue_chart
    insights:
      - ${ref(revenue-trend)}
    layout:
      title:
        text: "Revenue Trends by Category"
      xaxis:
        title:
          text: "Date"
        rangeslider:
          visible: true
      yaxis:
        title:
          text: "Revenue ($)"
        tickformat: "$,.0f"
      height: 400

  - name: customer_distribution_chart
    insights:
      - ${ref(customer-distribution)}

  - name: order_value_chart
    insights:
      - ${ref(order-value-median)}
      - ${ref(order-value-p95)}
    layout:
      title:
        text: "Median vs 95th Percentile Order Value"
      barmode: group

dashboards:
  - name: Sales Analytics Dashboard
    rows:
      - height: compact
        items:
          - markdown: |
              # Sales Performance Analytics
              Powered by DuckDB

      - height: large
        items:
          - width: 2
            chart: ${ref(main_revenue_chart)}
          - width: 1
            chart: ${ref(customer_distribution_chart)}

      - height: medium
        items:
          - width: 3
            chart: ${ref(order_value_chart)}
More DuckDB techniques for dashboards
Window functions for time series
A moving average, a month-over-month change and a z-score fit in one model:
name: model_example

models:
  - name: time_series_analysis
    sql: |
      WITH daily_metrics AS (
        SELECT
          DATE_TRUNC('day', timestamp) as day,
          metric_name,
          AVG(value) as daily_avg,
          STDDEV(value) as daily_stddev
        FROM metrics
        GROUP BY 1, 2
      )
      SELECT
        day,
        metric_name,
        daily_avg,
        -- 7-day moving average
        AVG(daily_avg) OVER (
          PARTITION BY metric_name
          ORDER BY day
          ROWS BETWEEN 6 PRECEDING AND CURRENT ROW
        ) as ma7,
        -- Month-over-month change
        daily_avg - LAG(daily_avg, 30) OVER (
          PARTITION BY metric_name
          ORDER BY day
        ) as mom_change,
        -- Z-score for anomaly detection
        (daily_avg - AVG(daily_avg) OVER (
          PARTITION BY metric_name
        )) / STDDEV(daily_avg) OVER (
          PARTITION BY metric_name
        ) as z_score
      FROM daily_metrics
Summary tables for complex aggregations
Pre-compute the expensive calculations. DuckDB has no materialized views, so store the result as a table and rebuild it after each load:
-- Run this in DuckDB to pre-compute the daily summary
CREATE OR REPLACE TABLE materialized_daily_summary AS
SELECT
  DATE_TRUNC('day', order_date) as day,
  product_category,
  COUNT(*) as orders,
  SUM(revenue) as total_revenue,
  COUNT(DISTINCT customer_id) as unique_customers
FROM sales
GROUP BY 1, 2;
Incremental loading
Load only the rows that arrived since the last run, then rebuild the summary table:
# Python script for incremental loading
import duckdb
from datetime import datetime, timedelta

def incremental_load():
    conn = duckdb.connect('./data/analytics.duckdb')

    # Get last loaded timestamp
    last_load = conn.execute("""
        SELECT MAX(loaded_at) FROM load_tracking
    """).fetchone()[0]

    # Load only new data
    conn.execute(f"""
        INSERT INTO sales
        SELECT * FROM read_parquet('s3://bucket/incremental/*.parquet')
        WHERE created_at > '{last_load}'
    """)

    # Update load tracking
    conn.execute(f"""
        INSERT INTO load_tracking VALUES ('{datetime.now()}')
    """)

    # Rebuild the summary table
    conn.execute("""
        CREATE OR REPLACE TABLE materialized_daily_summary AS
        SELECT
          DATE_TRUNC('day', order_date) as day,
          product_category,
          COUNT(*) as orders,
          SUM(revenue) as total_revenue,
          COUNT(DISTINCT customer_id) as unique_customers
        FROM sales
        GROUP BY 1, 2
    """)

    conn.commit()
    conn.close()

# Schedule this to run periodically
incremental_load()
Performance tuning
Query shape
Filter early and aggregate before you join:
name: dashboard_example

models:
  - name: optimized_dashboard_query
    sql: |
      -- Use CTEs for better optimization
      WITH filtered_sales AS (
        -- Filter early to reduce data volume
        SELECT * FROM sales
        WHERE order_date >= CURRENT_DATE - INTERVAL '30 days'
          AND status = 'completed'
      ),
      aggregated AS (
        -- Aggregate before joining
        SELECT
          product_id,
          COUNT(*) as sale_count,
          SUM(amount) as total_amount
        FROM filtered_sales
        GROUP BY product_id
      )
      SELECT
        p.product_name,
        p.category,
        a.sale_count,
        a.total_amount
      FROM aggregated a
      JOIN products p ON a.product_id = p.product_id
      WHERE a.sale_count > 10
      ORDER BY a.total_amount DESC
      LIMIT 100
Memory
Set a memory limit, a thread count and a spill directory:
# Configure DuckDB memory settings
import duckdb

conn = duckdb.connect('./data/analytics.duckdb', config={
    'memory_limit': '4GB',
    'threads': 4,
    'temp_directory': '/tmp/duckdb_temp'
})

# Enable progress bar for long-running queries
conn.execute("SET enable_progress_bar=true")
Partitioning
DuckDB tables are not partitioned. For large datasets, write partitioned Parquet files and let DuckDB skip the partitions a query does not need:
-- Write sales as Hive-partitioned Parquet files
COPY (
    SELECT *, year(order_date) AS year, month(order_date) AS month
    FROM sales
) TO 'data/sales_partitioned' (FORMAT parquet, PARTITION_BY (year, month));

-- Read them back; filters on year and month prune whole partitions
SELECT * FROM read_parquet('data/sales_partitioned/*/*/*.parquet', hive_partitioning = true)
WHERE year = 2025 AND month = 6;
Deployment patterns
Local development
The default, and the right fit for prototyping and dbt™ local development:
# Clone your Visivo project
git clone your-project

# Set up DuckDB database
python setup_duckdb.py

# Start Visivo development server
visivo serve

# Your dashboard is now running locally with full data
Edge deployment
For regional analytics, ship each region its own DuckDB file at the same path. The project stays identical and each deployment reads only its region's data:
name: model_example

# Regional DuckDB configuration
sources:
  - name: regional_duck
    type: duckdb
    database: ./data/region.duckdb

models:
  - name: regional_metrics
    source: ${ref(regional_duck)}
    sql: |
      SELECT * FROM sales
Hybrid architecture
Keep hot data in DuckDB and history in the warehouse. Each model runs on its own source, and one chart plots both Insights:
name: model_example

sources:
  - name: local_duck
    type: duckdb
    database: ./data/analytics.duckdb

  - name: warehouse
    type: snowflake
    account: ${env.SNOWFLAKE_ACCOUNT}
    warehouse: ANALYTICS
    database: ANALYTICS
    username: ${env.SNOWFLAKE_USER}
    password: ${env.SNOWFLAKE_PASSWORD}

models:
  # Recent data from DuckDB (fast)
  - name: recent_sales
    source: ${ref(local_duck)}
    sql: |
      SELECT order_date, SUM(amount) AS revenue
      FROM sales
      WHERE order_date >= CURRENT_DATE - INTERVAL '7 days'
      GROUP BY 1

  # Historical from the warehouse (slower but comprehensive)
  - name: historical_sales
    source: ${ref(warehouse)}
    sql: |
      SELECT order_date, SUM(amount) AS revenue
      FROM sales
      WHERE order_date < CURRENT_DATE - 7
        AND order_date >= CURRENT_DATE - 90
      GROUP BY 1

insights:
  - name: recent-revenue
    props:
      type: scatter
      mode: lines
      name: Last 7 days
      x: ?{ ${ref(recent_sales).order_date} }
      y: ?{ ${ref(recent_sales).revenue} }

  - name: historical-revenue
    props:
      type: scatter
      mode: lines
      name: Days 8 to 90
      x: ?{ ${ref(historical_sales).order_date} }
      y: ?{ ${ref(historical_sales).revenue} }

charts:
  - name: revenue-hot-and-history
    insights:
      - ${ref(historical-revenue)}
      - ${ref(recent-revenue)}
Testing the dashboard
Tests live in the project YAML, assert on the values your Insights compute, and run with visivo test:
tests:
  - name: revenue-trend-has-data
    assertions:
      - ">{ len( ${ref(revenue-trend).props.y} ) > 0 }"

  - name: no-negative-revenue
    assertions:
      - ">{ numpy.min( ${ref(revenue-trend).props.y} ) >= 0 }"
Getting started
The quickstart:
# Install Visivo
pip install visivo

# Create a new project (init starts the dev server for you)
visivo init --project-dir my-duckdb-dashboard

# Add the DuckDB source from above to project.visivo.yml, then
# start developing again from the project folder
cd my-duckdb-dashboard
visivo serve

# Open http://localhost:8000 (change the port with --port)
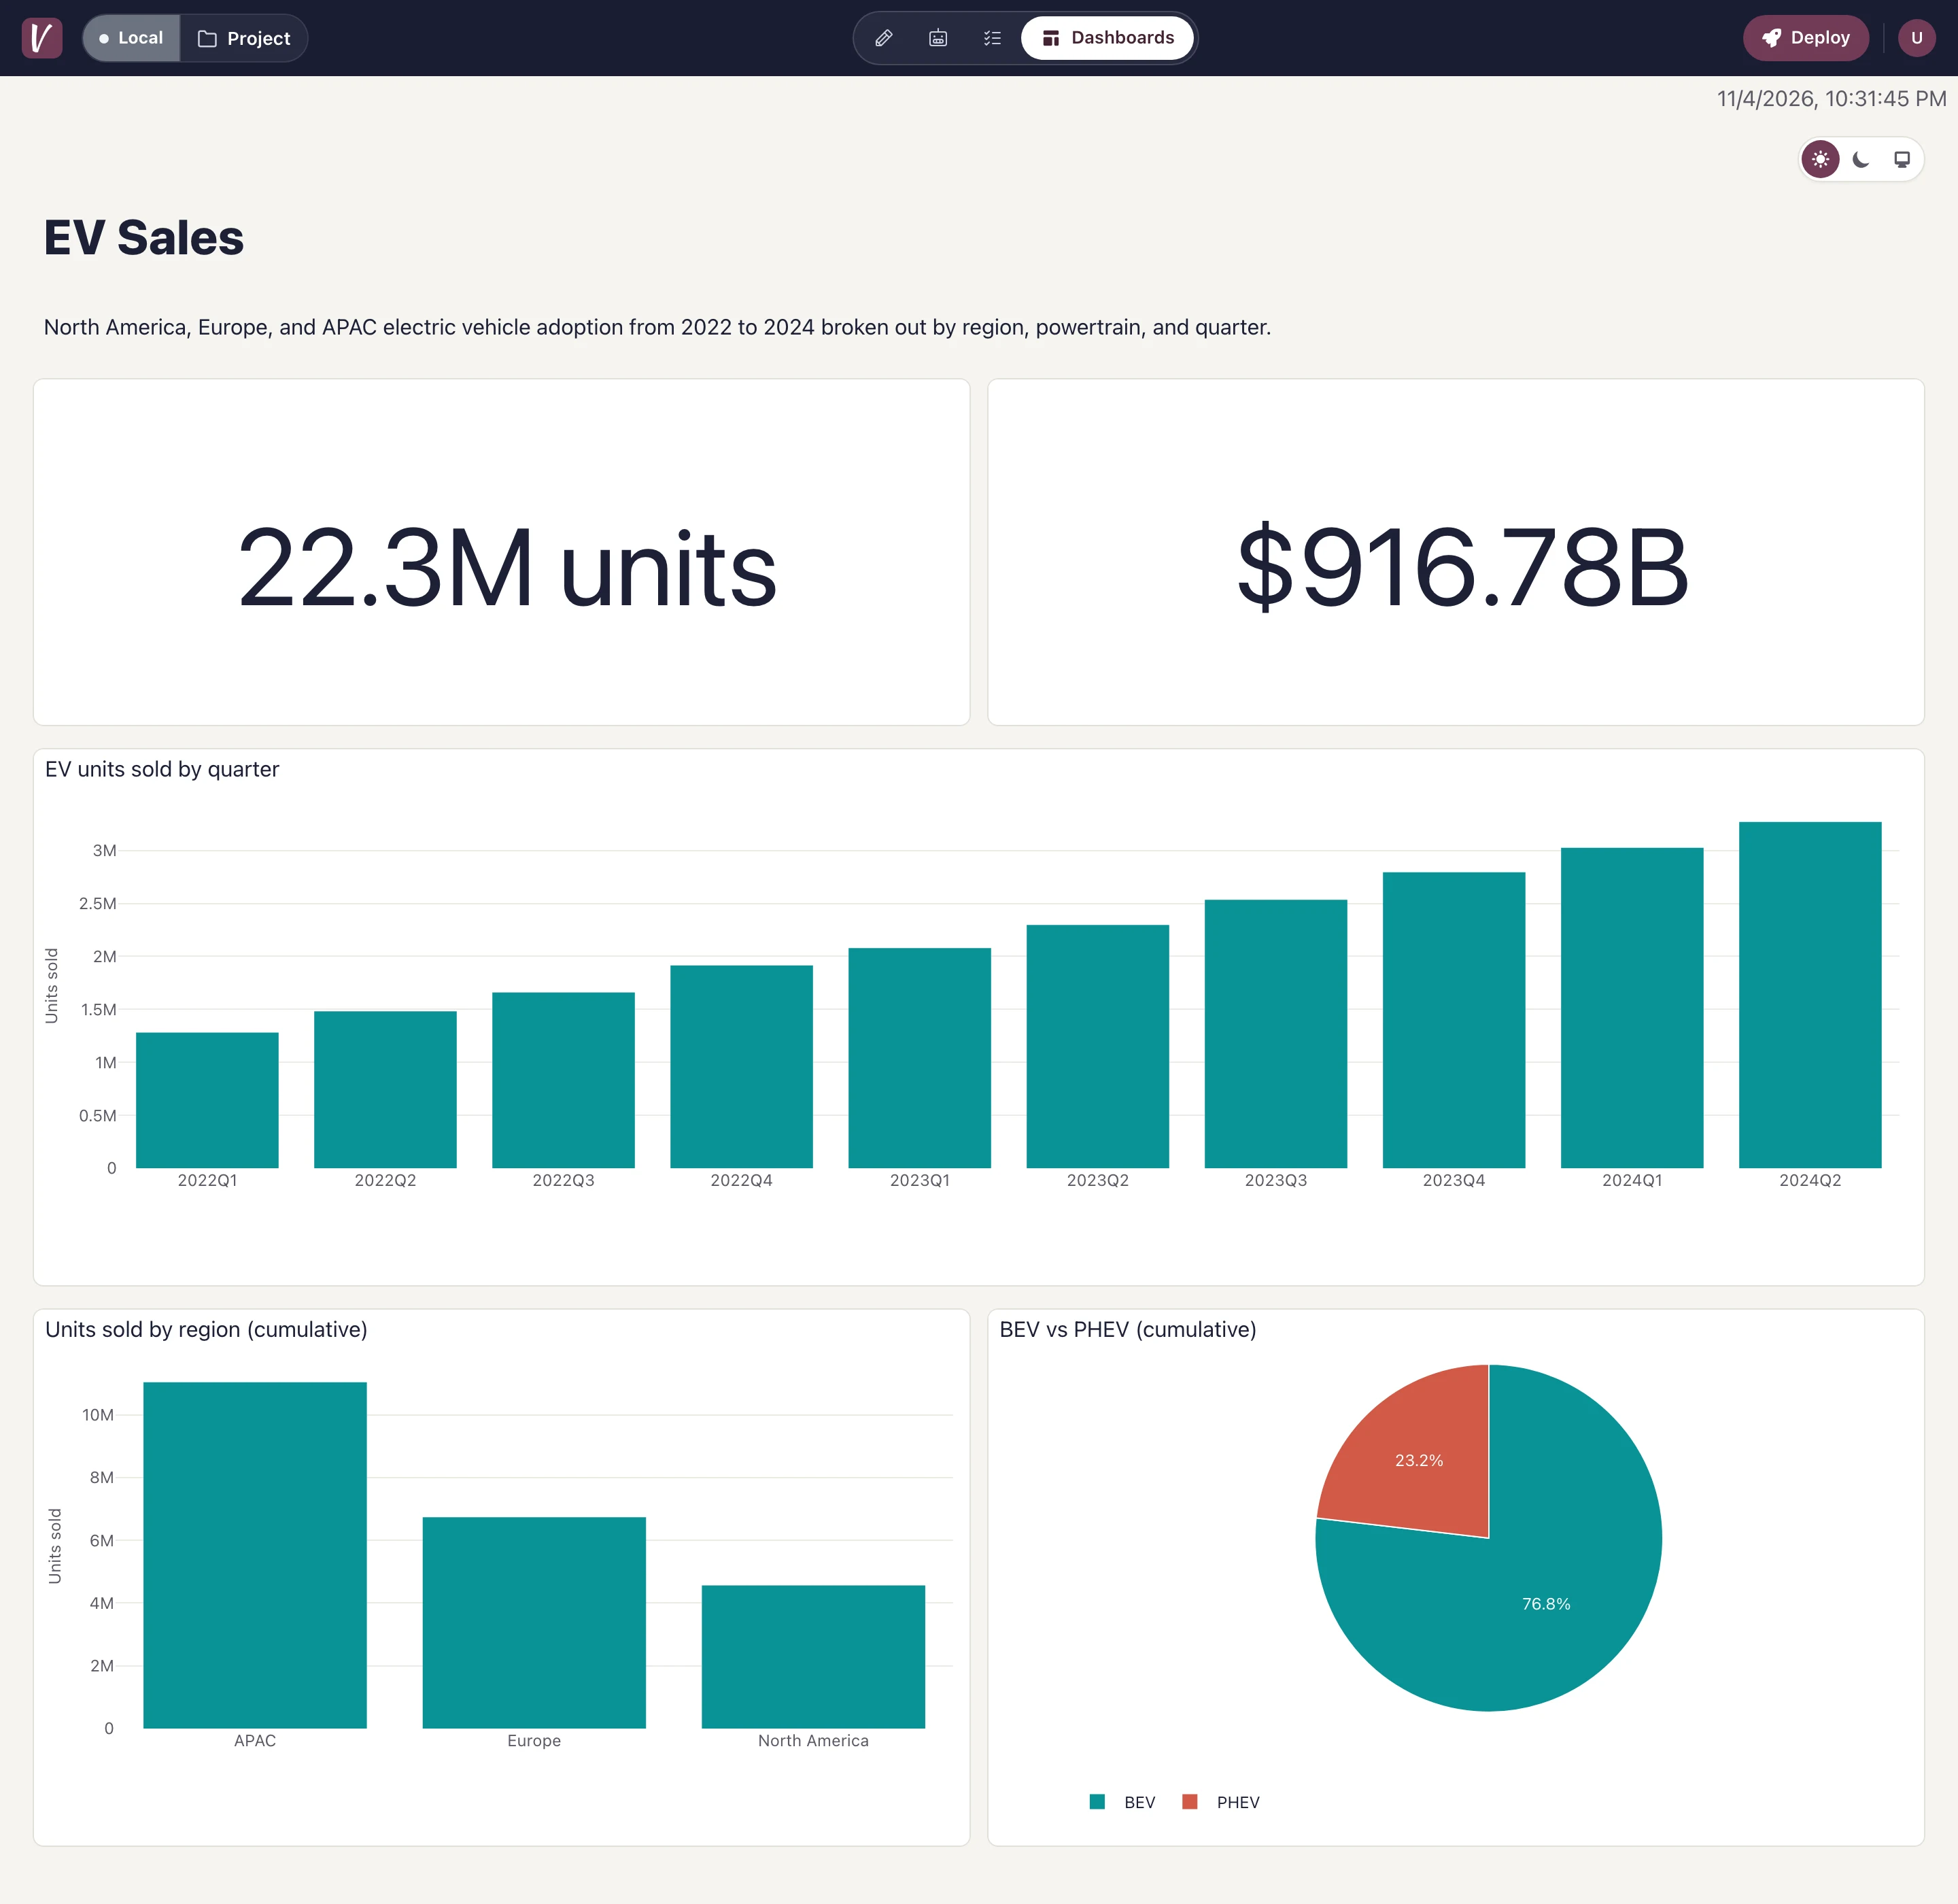 The ev-sales example (
visivo init --example ev-sales) reads a local DuckDB file and is served by visivo serve in Visivo 2.3.0.
Production checklist
- Use Parquet files for compression and query performance
- Partition large tables by date or another high-cardinality column
- Create indexes on frequently filtered columns
- Pre-compute complex aggregations into summary tables so dashboards load fast
- Load incrementally so each refresh reads only new rows
- Monitor query performance and fix the slow ones
- Back up your DuckDB files
Conclusion
You do not need a warehouse to get fast dashboards. A DuckDB file and a Visivo project on one machine cover most analytical workloads, and the whole project is YAML in Git.
Related reading: customizable embedded analytics, faster feedback cycles, and visualizations as code.
To try it:
# Install and get started
curl -fsSL https://visivo.sh | bash
visivo init --project-dir my-duckdb-project
The Visivo documentation has the full source reference, and app.visivo.io is where you deploy a DuckDB-backed project to Visivo Cloud.
The slow part of most dashboards is the round trip to a remote warehouse. Put the data next to the query and that trip disappears.